How the visual reads your data
The row-to-diagram model every diagram type shares: nodes, connections, reading direction, repeated rows and exact identifiers.
One row per connection
The visual reads a table. Each row names a node in the column mapped to Node ID and, optionally, the node it connects to in the column mapped to Connected node. A node that connects to several others appears on several rows, one per connection.
| Node ID | Connected node | Node type | Label |
|---|---|---|---|
| TOP | Top Event | Online ordering unavailable | |
| G1 | TOP | OR Gate | Any cause |
| P1 | G1 | Basic Event | Database server fails |
| P2 | G1 | Basic Event | Payment service fails |
Rows that share a Node ID become one node. A blank Connected node, including a cell holding only spaces, adds no connection on that row and is not an error.
Which way a connection runs
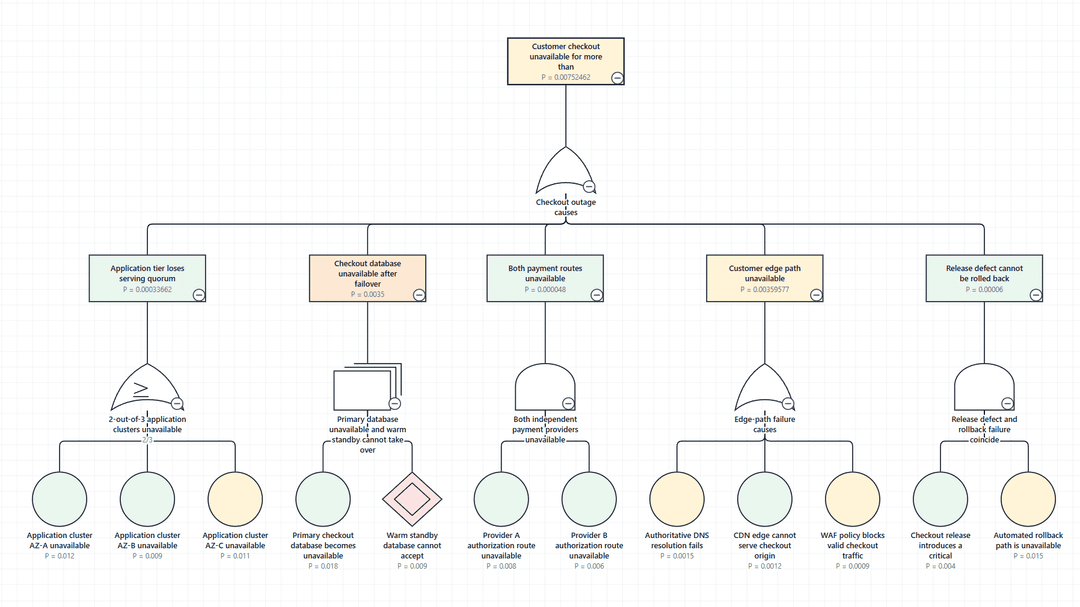
A connection has a direction, and each diagram type starts from the reading its data usually takes. A fault tree row names its parent, the event above it, so the connected node comes before the row. A reliability block diagram row names the next block along the path, so the connected node comes after the row.
| Diagram type | Connected node is read as | Default orientation |
|---|---|---|
| Fault Tree Analysis | Comes before this row | Top to bottom |
| Bow-Tie Risk Analysis | Comes after this row | Left to right |
| Event Tree Analysis | Comes before this row | Left to right |
| Reliability Block Diagram | Comes after this row | Left to right |
| Goal Structuring Notation | Comes after this row | Top to bottom |
| Markov State Diagram | Comes after this row | Left to right |
If your table is written the other way round, change Connection column → Reads as on the Data Mapping tab. Read the wrong way, every connection runs backwards: the diagram inverts, and the nodes that should start it are reported as having no inputs.
Repeated rows and snapshots
A table that restates the same structure many times, one copy per month or per snapshot, draws each node and connection once. Every row behind a node is kept, so selecting the node cross-filters the report against all of them.
When rows for the same node disagree about its details, the first row is used and a diagnostic names the conflict.
Structure and values
Mapped columns do one of two jobs. Structural roles, such as Node ID, Connected node, Node type, Relationship type and Diagram ID, decide what is drawn. Value roles, such as Probability, Failure rate, Status and Health, appear in tooltips and the Node Inspector, are checked where the method has rules for them, and can drive conditional formatting.
Any other column bound to the visual is kept on the node as it is, without being mapped to a role. It appears in the Node Inspector and can drive conditional formatting and value annotations. Columns in Values or Tooltips also appear in tooltips.
Identifiers must match exactly
A connection joins only when the Connected node matches a Node ID exactly. Numeric identifiers join as numbers. An identifier with a stray space does not match; the validation message quotes both values so the difference can be found.